java实现 PageRank算法

文章目录
PageRank算法是Google的核心搜索算法,在所有链接型文档搜索中有极大用处,而且在我们的各种关联系统中都有好的用法,比如专家评分系统,微博搜索/排名,SNS系统等。
PageRank算法的依据或思想:
1,被重要的网页链接的越多(外链) ,此网页就越重要
2,此网页对外的链接越少越重要
这两个依据不能是独立的,是需要一起考虑的。但是问题来了,我们怎样判断本网页的外链是很重要的呢?循环判断?那不死循环了?
解决办法是:给定阀值,让循环在此临界处停止。
首先,我们准备了7个测试网页,这几个网页的链接情况如下:
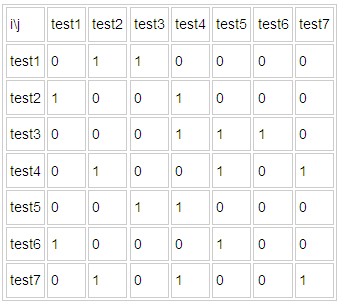
表格的意思是 test1链接到 test2,test3 ....依次类推 ,我们大致的根据上面两个原则可以猜一下,哪个将会是排名第一的网页?哪个最不重要?
貌似是test4和test6?
下面我们看看怎样用java实现PageRank算法。
首先创建html实体表示类,代码如下:
/**
 * 网页entity
 *
 * @author  afei
 *
 */
class HtmlEntity {

    private String path;
    private String content;
    /* 外链(本页面链接的其他页面) */
    private List<String> outLinks = new ArrayList<String>();

    /* 内链(另外页面链接本页面) */
    private List<String> inLinks = new ArrayList<String>();

    private double pr;

    public String getPath() {
        return path;
    }

    public void setPath(String path) {
        this.path = path;
    }

    public String getContent() {
        return content;
    }

    public void setContent(String content) {
        this.content = content;
    }

    public double getPr() {
        return pr;
    }

    public void setPr(double pr) {
        this.pr = pr;
    }

    public List<String> getOutLinks() {
        return outLinks;
    }

    public void setOutLinks(List<String> outLinks) {
        this.outLinks = outLinks;
    }

    public List<String> getInLinks() {
        return inLinks;
    }

    public void setInLinks(List<String> inLinks) {
        this.inLinks = inLinks;
    }

}
核心算法代码如下:
/**
 * pagerank算法实现
 *
 * @author  afei
 *
 */
public class HtmlPageRank {

    /* 阀值 */
    public static double MAX = 0.00000000001;

    /* 阻尼系数 */
    public static double alpha = 0.85;

    public static String htmldoc = "D:\\workspace\\Test\\WebRoot\\htmldoc";

    public static Map<String, HtmlEntity> map = new HashMap<String, HtmlEntity>();

    public static List<HtmlEntity> list = new ArrayList<HtmlEntity>();

    public static double[] init;

    public static double[] pr;

    public static void main(String[] args) throws Exception {
        loadHtml();
        pr = doPageRank();
        while (!(checkMax())) {
            System.arraycopy(pr, 0, init, 0, init.length);
            pr = doPageRank();
        }
        for (int i = 0; i < pr.length; i++) {
            HtmlEntity he=list.get(i);
            he.setPr(pr[i]);
        }

        List<HtmlEntity> finalList=new ArrayList<HtmlEntity>();
        Collections.sort(list,new Comparator(){

            public int compare(Object o1, Object o2) {
                HtmlEntity h1=(HtmlEntity)o1;
                HtmlEntity h2=(HtmlEntity)o2;
                int em=0;
                if(h1.getPr()> h2.getPr()){
                    em=-1;
                }else{
                    em=1;
                }
                return em;
            }

        });

        for(HtmlEntity he:list){
            System.out.println(he.getPath()+" : "+he.getPr());
        }

    }

    /* pagerank步骤 */

    /**
     * 加载文件夹下的网页文件,并且初始化pr值(即init数组),计算每个网页的外链和内链
     */
    public static void loadHtml() throws Exception {
        File file = new File(htmldoc);
        File[] htmlfiles = file.listFiles(new FileFilter() {

            public boolean accept(File pathname) {
                if (pathname.getPath().endsWith(".html")) {
                    return true;
                }
                return false;
            }

        });
        init = new double[htmlfiles.length];
        for (int i = 0; i < htmlfiles.length; i++) {
            File f = htmlfiles[i];
            BufferedReader br = new BufferedReader(new InputStreamReader(
                    new FileInputStream(f)));
            String line = br.readLine();
            StringBuffer html = new StringBuffer();
            while (line != null) {
                line = br.readLine();
                html.append(line);
            }
            HtmlEntity he = new HtmlEntity();
            he.setPath(f.getAbsolutePath());
            he.setContent(html.toString());
            Parser parser = Parser.createParser(html.toString(), "gb2312");
            HtmlPage page = new HtmlPage(parser);
            parser.visitAllNodesWith(page);
            NodeList nodelist = page.getBody();
            nodelist = nodelist.extractAllNodesThatMatch(
                    new TagNameFilter("A"), true);
            for (int j = 0; j < nodelist.size(); j++) {
                LinkTag outlink = (LinkTag) nodelist.elementAt(j);
                he.getOutLinks().add(outlink.getAttribute("href"));
            }

            map.put(he.getPath(), he);
            list.add(he);
            init[i] = 0.0;

        }
        for (int i = 0; i < list.size(); i++) {
            HtmlEntity he = list.get(i);
            List<String> outlink = he.getOutLinks();
            for (String ol : outlink) {
                HtmlEntity he0 = map.get(ol);
                he0.getInLinks().add(he.getPath());
            }
        }

    }

    /**
     * 计算pagerank
     *
     * @param init
     * @param alpho
     * @return
     */
    private static double[] doPageRank() {
        double[] pr = new double[init.length];
        for (int i = 0; i < init.length; i++) {
            double temp = 0;
            HtmlEntity he0 = list.get(i);
            for (int j = 0; j < init.length; j++) {
                HtmlEntity he = list.get(j);
                // 计算对本页面链接相关总值
                if (i != j && he.getOutLinks().size() != 0
                        && he.getOutLinks().contains(he0.getPath())/*he0.getInLinks().contains(he.getPath())*/) {
                    temp = temp + init[j] / he.getOutLinks().size();
                }

            }
            //经典的pr公式
            pr[i] = alpha + (1 - alpha) * temp;
        }
        return pr;
    }

    /**
     * 判断前后两次的pr数组之间的差别是否大于我们定义的阀值 假如大于,那么返回false,继续迭代计算pr
     *
     * @param pr
     * @param init
     * @param max
     * @return
     */
    private static boolean checkMax() {
        boolean flag = true;
        for (int i = 0; i < pr.length; i++) {
            if (Math.abs(pr[i] - init[i]) > MAX) {
                flag = false;
                break;
            }
        }
        return flag;
    }


}
直接运行算法类,得到的结果如下:
D:\workspace\Test\WebRoot\htmldoc\test4.html : 1.102472450686259
D:\workspace\Test\WebRoot\htmldoc\test5.html : 1.068131842865856
D:\workspace\Test\WebRoot\htmldoc\test2.html : 1.0249590169406457
D:\workspace\Test\WebRoot\htmldoc\test3.html : 1.0046891014946187
D:\workspace\Test\WebRoot\htmldoc\test1.html : 0.9943895104008613
D:\workspace\Test\WebRoot\htmldoc\test7.html : 0.9051236225340915
D:\workspace\Test\WebRoot\htmldoc\test6.html : 0.9002344550746025
此算法可以无限改造,以满足自身要求。
By 阿飞哥 转载请说明
评论
登录后参与技术讨论,分享你的经验与见解。
登录 / 注册⭐️ Admin快速开发: https://show.cool-admin.com/
赞 0⭐️ 官方文档: https://cool-js.com
赞 0⭐️ chatgpt在线体验: https://cool-js.com/ai/chat-vip/index.html?r=helloworld
赞 0