MapReduce简单使用

文章目录
1、启动hadoop工程
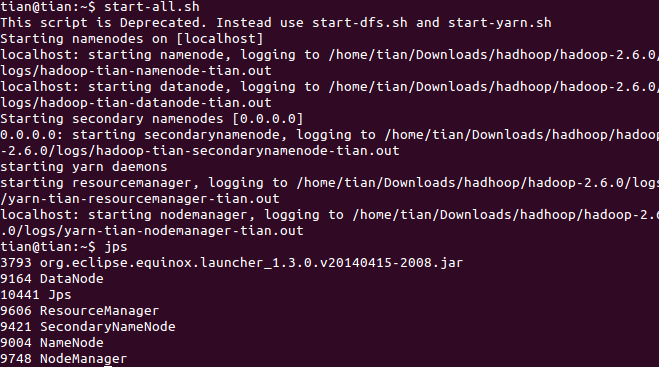
2、MapReduce统计文本单词数量
public class WordCount {

    private static class WordMapper extends
            Mapper<LongWritable, Text, Text, IntWritable> {

        @Override
        protected void map(LongWritable key, Text value,
                Mapper<LongWritable, Text, Text, IntWritable>.Context context)
                throws IOException, InterruptedException {

            String string = value.toString();
            String[] strs = string.split(" ");
            for (String str : strs) {
                context.write(new Text(str), new IntWritable(1));
            }

        }

    }

    private static class WordReduce extends
            Reducer<Text, IntWritable, Text, IntWritable> {
        // key 单词 //value:{1,1}

        @Override
        protected void reduce(Text key, Iterable<IntWritable> values,
                Reducer<Text, IntWritable, Text, IntWritable>.Context context)
                throws IOException, InterruptedException {

            int count = 0;
            for (IntWritable value : values) {
                count += value.get();
            }

            context.write(key, new IntWritable(count));

        }

    }

    public static void main(String[] args) throws IOException,
            ClassNotFoundException, InterruptedException {

        Configuration configuration = HadoopConfig.getConfiguration();
        Job job = Job.getInstance(configuration, "统计单词数目");
        job.setJarByClass(WordCount.class);
        job.setMapperClass(WordMapper.class);
        job.setMapOutputKeyClass(Text.class);
        job.setMapOutputValueClass(IntWritable.class);
        job.setReducerClass(WordReduce.class);
        job.setOutputKeyClass(Text.class);
        job.setOutputValueClass(IntWritable.class);

        FileInputFormat.addInputPath(job, new Path("/data"));
        FileOutputFormat.setOutputPath(job, new Path("/ouput"));
        job.waitForCompletion(true);
        System.exit(job.waitForCompletion(true) ? 0 : 1);

    }
2、MapReduce排除文本重复数据
public class Dup {

    private static class DupMapper extends
            Mapper<LongWritable, Text, Text, NullWritable> {

        @Override
        protected void map(LongWritable key, Text value,
                Mapper<LongWritable, Text, Text, NullWritable>.Context context)
                throws IOException, InterruptedException {

            context.write(new Text(value), NullWritable.get());

        }

    }

    private static class DupReduce extends
            Reducer<Text, NullWritable, Text, NullWritable> {

        @Override
        protected void reduce(Text key, Iterable<NullWritable> values,
                Reducer<Text, NullWritable, Text, NullWritable>.Context context)
                throws IOException, InterruptedException {

            context.write(new Text(key), NullWritable.get());

        }

    }

    public static void main(String[] args) throws IOException,
            ClassNotFoundException, InterruptedException {

        Configuration configuration = HadoopConfig.getConfiguration();
        Job job = Job.getInstance(configuration, "去重");

        job.setJarByClass(Dup.class);
        job.setMapperClass(DupMapper.class);

        job.setMapOutputKeyClass(Text.class);
        job.setMapOutputValueClass(NullWritable.class);
        job.setOutputKeyClass(Text.class);
        job.setOutputValueClass(NullWritable.class);

        job.setReducerClass(DupReduce.class);
        FileInputFormat.addInputPath(job, new Path("/data"));
        FileOutputFormat.setOutputPath(job, new Path("/dup"));
        job.waitForCompletion(true);
        System.exit(job.waitForCompletion(true) ? 0 : 1);

    }
3、MapReduce实线文本数据的简单排序
public class Sort {

    private static class SortMapper extends
            Mapper<LongWritable, Text, IntWritable, IntWritable> {
           //输出,输入
        @Override
        protected void map(
                LongWritable key,
                Text value_text,
                Mapper<LongWritable, Text, IntWritable, IntWritable>.Context context)
                throws IOException, InterruptedException {

            int value = Integer.parseInt(value_text.toString());
            context.write(new IntWritable(value), new IntWritable(1));

        }

    }

    private static class SortReduce extends
            Reducer<IntWritable, IntWritable, IntWritable, NullWritable> {

        @Override
        protected void reduce(
                IntWritable key,
                Iterable<IntWritable> values,
                Reducer<IntWritable, IntWritable, IntWritable, NullWritable>.Context context)
                throws IOException, InterruptedException {

            for (IntWritable value : values) {
                context.write(key, NullWritable.get());
            }

        }

    }

    public static void main(String[] args) throws IOException,
            ClassNotFoundException, InterruptedException {

        Configuration configuration = HadoopConfig.getConfiguration();
        Job job = Job.getInstance(configuration, "排序");

        job.setJarByClass(Sort.class);
        job.setMapperClass(SortMapper.class);

        job.setMapOutputKeyClass(IntWritable.class);
        job.setMapOutputValueClass(IntWritable.class);
        job.setOutputKeyClass(IntWritable.class);
        job.setOutputValueClass(NullWritable.class);

        job.setReducerClass(SortReduce.class);
        FileInputFormat.addInputPath(job, new Path("/data"));
        FileOutputFormat.setOutputPath(job, new Path("/sort"));
        job.waitForCompletion(true);

    }
4、MapReduce实线单表连接
文本数据如下:
child parent
tom lucy
tom jack
lucy mary
lucy ben
public class Single {

    private static class SingleMapper extends
            Mapper<LongWritable, Text, Text, Text> {

        @Override
        protected void map(LongWritable key, Text value,
                Mapper<LongWritable, Text, Text, Text>.Context context)
                throws IOException, InterruptedException {

            String string = value.toString();
            if (!string.contains("child")) {

                String[] strings = string.split(" ");
                context.write(new Text(strings[0]), new Text(strings[1] + ":1"));
                context.write(new Text(strings[1]), new Text(strings[0] + ":2"));

            }
        }
    }

    // reduce是执行key的次数
    private static class SingleReduce extends Reducer<Text, Text, Text, Text> {

        @Override
        protected void reduce(Text key, Iterable<Text> values,
                Reducer<Text, Text, Text, Text>.Context context)
                throws IOException, InterruptedException {

            List<String> left = Lists.newArrayList();
            List<String> right = Lists.newArrayList();

            for (Text value : values) {

                String[] strings = value.toString().split(":");

                if (strings[1].equals("1")) {
                    right.add(strings[0]);
                } else {
                    left.add(strings[0]);
                }
            }

            for (String lef : left) {
                for (String rig : right) {
                    context.write(new Text(lef), new Text(rig));
                }
            }

        }

    }

    public static void main(String[] args) throws IOException,
            ClassNotFoundException, InterruptedException {

        Configuration configuration = HadoopConfig.getConfiguration();
        Job job = Job.getInstance(configuration, "单表连接");

        job.setJarByClass(Sort.class);
        job.setMapperClass(SingleMapper.class);

        job.setMapOutputKeyClass(Text.class);
        job.setMapOutputValueClass(Text.class);
        job.setOutputKeyClass(Text.class);
        job.setOutputValueClass(Text.class);

        job.setReducerClass(SingleReduce.class);
        FileInputFormat.addInputPath(job, new Path("/data"));
        FileOutputFormat.setOutputPath(job, new Path("/single"));
        job.waitForCompletion(true);

    }
输出结果如下:
grandchild grandparent //额外加入的,表达思路
tom mary
tom ben
评论
登录后参与技术讨论,分享你的经验与见解。
登录 / 注册暂无评论