tesseract ocr node api使用

文章目录
原文链接: tesseract ocr node api使用
安装
https://github.com/UB-Mannheim/tesseract/wiki
https://github.com/tesseract-ocr/tesseract/wiki
https://www.npmjs.com/package/tesseract.js
目前用过的在线api有百度ocr, 腾讯ocr, 这两个半斤八两吧感觉
第一次使用会有点慢, 是因为需要下载数据文件
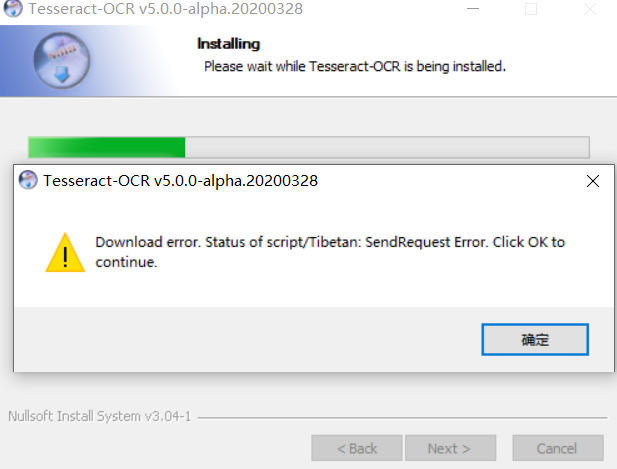
windows
https://github.com/UB-Mannheim/tesseract/wiki
ubuntu
sudo apt install tesseract-ocr
sudo apt install libtesseract-dev


sudo vi /etc/apt/sources.list

Copy the first line "deb http://archive.ubuntu.com/ubuntu bionic main" and paste it as shown below on the next line.
If you are using a different release of ubuntu, then replace bionic with the respective release name.

deb http://archive.ubuntu.com/ubuntu bionic universe
安装
yarn add tesseract.js
使用
// sudo apt install tesseract-ocr -y
// sudo apt install libtesseract-dev -y

// import Tesseract from "tesseract.js";
const Tesseract = require("tesseract.js");
// Tesseract.recognize("./word.png", "eng", {
Tesseract.recognize("./output.png", "eng", {
  logger: (m) => console.log(m),
}).then(({ data: { text } }) => {
  console.log("text:", text);
});
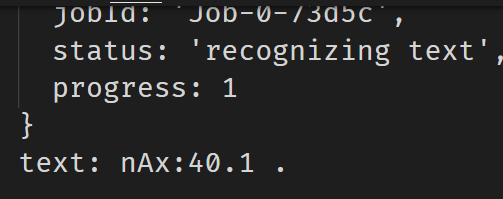
好像有点不太行...

评论
登录后参与技术讨论,分享你的经验与见解。
登录 / 注册暂无评论