66行代码爬取指定城市当前天气状况

文章目录
本次是一个爬虫案例,要爬的站点是这个:http://www.weather.com.cn/,目标是爬取指定城市当前的天气状况。
分析网站
首先来到目标数据的网页, 以山东济南为例:http://www.weather.com.cn/weather1d/101120101.shtml
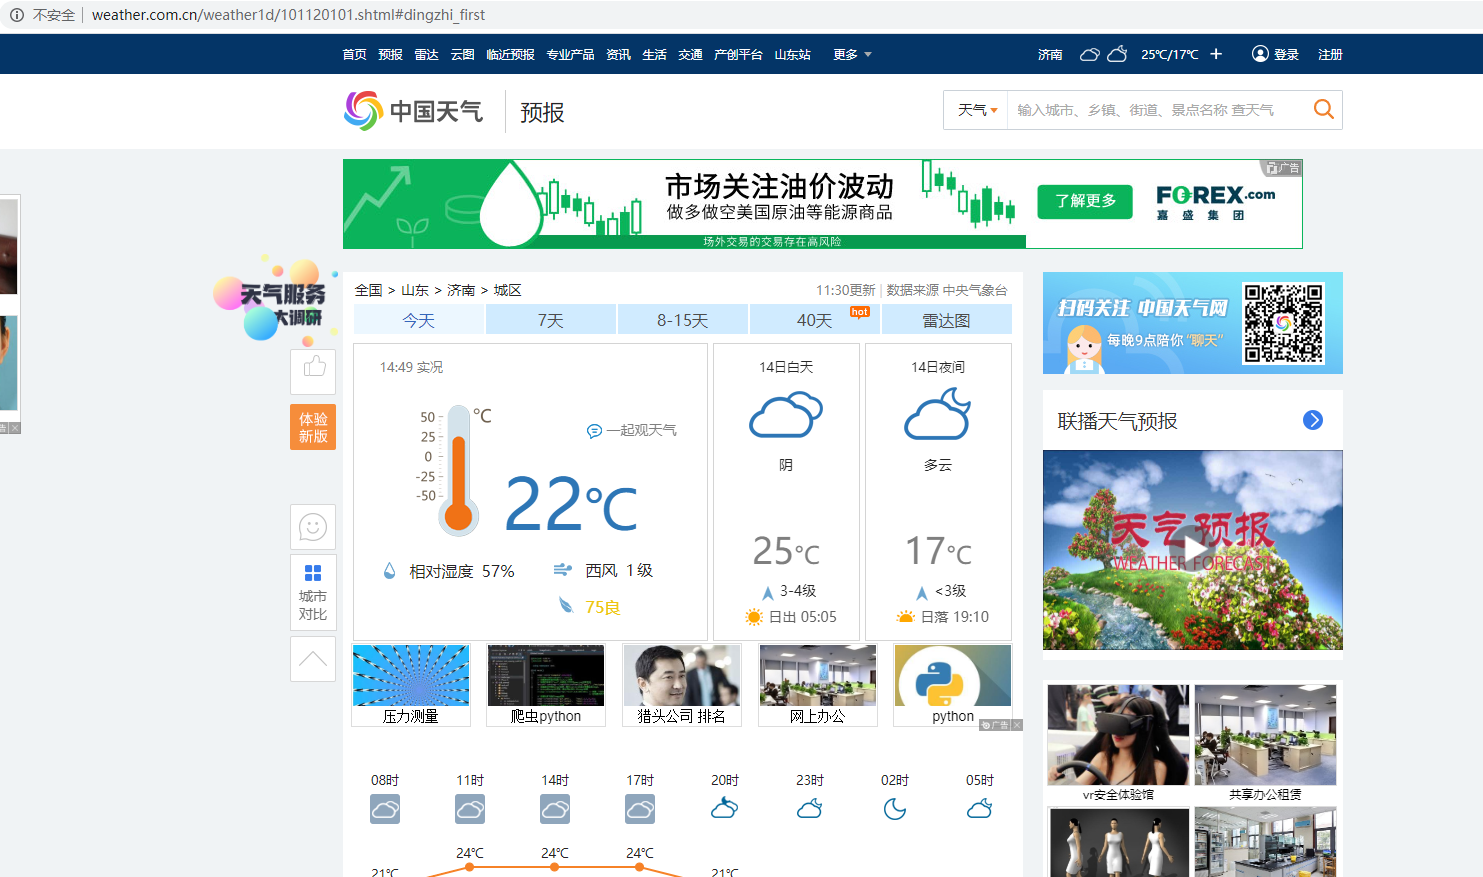
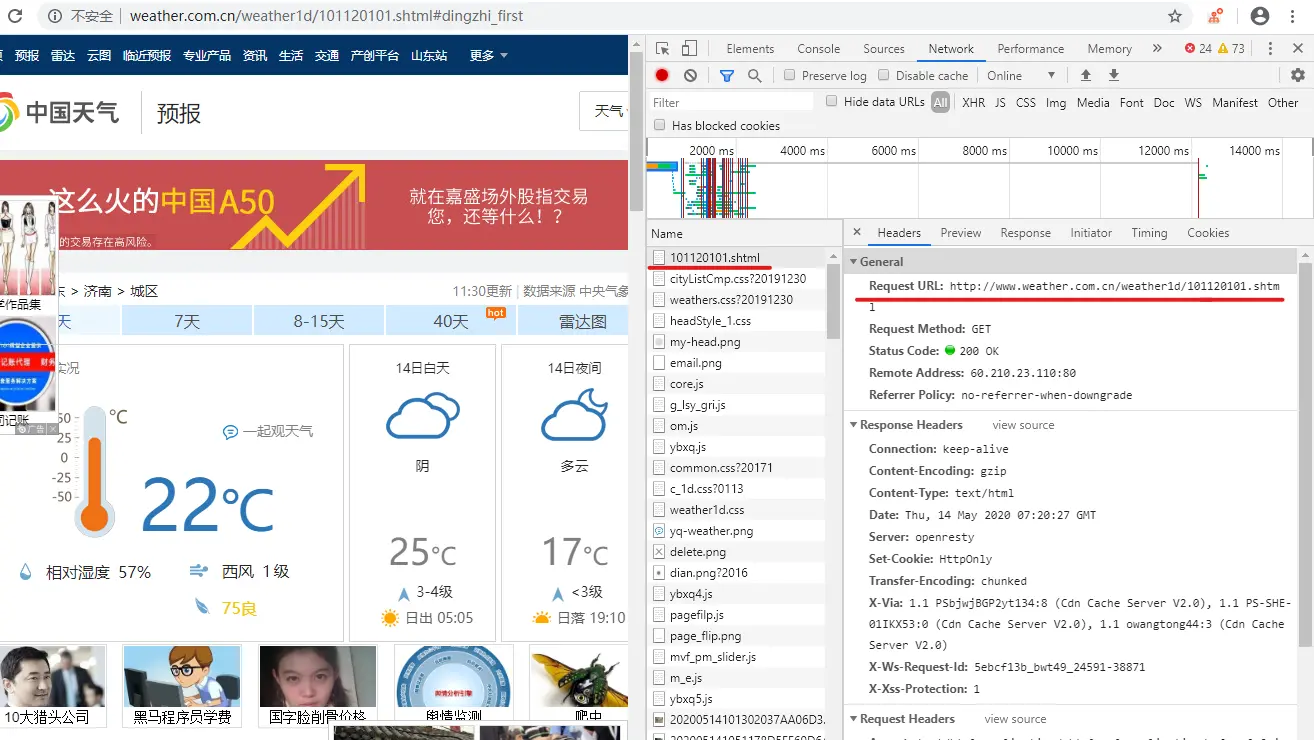
很显然,这个页面中有好多图表,大多数据呢,也都是动态获取的,对于这种页面,我们需要按下F12,找到network, 抓一下包,就会发现,当刷新当前页面的时候,浏览器会发出很多请求,都可以很清楚的看到请求头和请求体。我在其中发现了这个请求 http://www.weather.com.cn/weather1d/101120101.shtml
查看Response后发现想要的天气信息都在响应体里面。
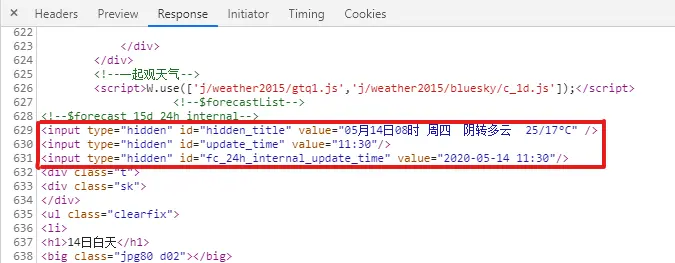
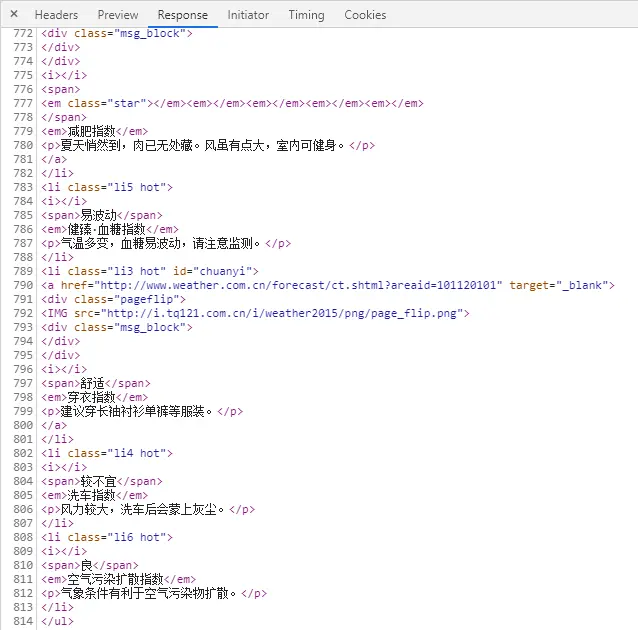
分析完网站,我们发现,想要的天气信息其实都能拿到,只需要发请求,然后用一定的规则去解析网页。拿到我们所需的数据即可。
代码实现
我这里解析网页用的re正则表达式,当然也可以使用其他方式,代码整体不难,几乎没有坑,在这里就不解释了,直接放代码:
import requests import re class WeatherSpider(object): _""" _ 天气爬虫 """ def __init__(self): self.headers = { 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko)' ' Chrome/81.0.4044.43 Safari/537.36' } self.url = 'http://www.weather.com.cn/weather1d/101120101.shtml' def spider(self): response = requests.get(url=self.url, headers=self.headers) content = response.content.decode('utf-8') # 使用re.compile()根据包含的正则表达式的字符串创建模式对象 re_weather = re.compile('') re_update_time = re.compile('') weather = re_weather.findall(content) update_time = re_update_time.findall(content) print(weather[0]) print('更新时间:', update_time[0]) life_index = re.compile('<li class="li. hot".*?\n.(.*?)\n(.*?)\n
' '(.*?)
.*?\n', re.S) # re.S使 . 匹配包括换行在内的所有字符 more_weather = life_index.findall(content) # print(more_weather) for item in more_weather: print(item[1], ':', item[0]+",", item[2])获取城市编号
这是以济南为例的,那就有人说,怎么爬取指定城市的天气呢?那也有办法,我们仔细观察一下http://www.weather.com.cn/weather1d/101120101.shtml这个链接,发现了101120101这串数字,那我就大胆猜测一下,101120101就是该网站给济南的编号,就是代表的济南。
事实验证就是这样,每个城市的编号都不一样,那我们只要获取到指定城市的编号就可以获取到该城市的天气,那要怎么获取指定城市的编号呢?
我在主页发现了这个城市搜索栏。发现了搜索时会发送这个链接 http://toy1.weather.com.cn/search?cityname=济南:
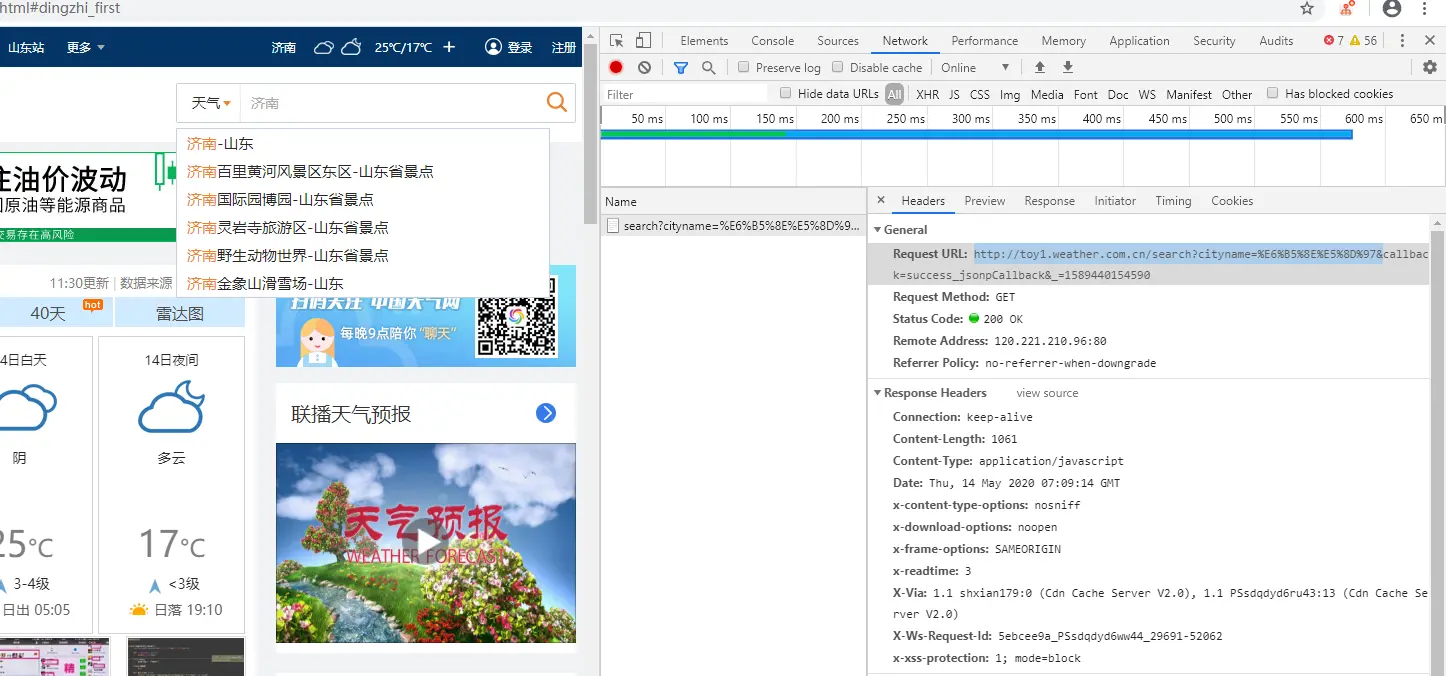
用postman试了一下,果然,在返回中发现了济南的编号101120101。
](http://toy1.weather.com.cn/search?cityname=%E6%B5%8E%E5%8D%!%5B%5D(https://oscimg.oschina.net/oscnet/up-989849f1468608888e92185225dd6cc4b82.png))
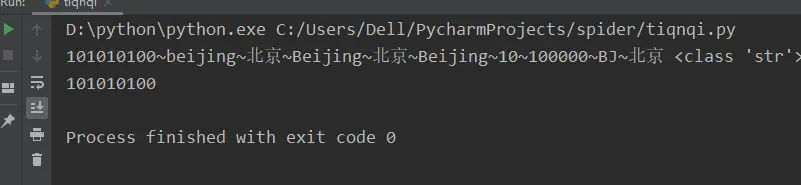
下面这段代码就是模拟了这个请求,然后处理了一下返回体,得到了城市编号。
def get_no(cityname): response = requests.get(url="http://toy1.weather.com.cn/search?cityname=" + cityname) content = response.content.decode('utf-8') content_t = eval(content)[0]["ref"] print(content_t, type(content_t)) city_no = content_t.split("~")[0] print(city_no) return city_no
代码整合
下面将两段代码整合一下:
import requests import re
class WeatherSpider(object): _""" _ 天气爬虫 """ def __init__(self): self.headers = { 'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko)' ' Chrome/81.0.4044.43 Safari/537.36' } self.url = 'http://www.weather.com.cn/weather1d/%s.shtml' self.no_url = "http://toy1.weather.com.cn/search?cityname=" def spider(self, city_no): try: print("发送请求:", self.url %city_no) response = requests.get(url=self.url %city_no, headers=self.headers) content = response.content.decode('utf-8') # 使用re.compile()根据包含的正则表达式的字符串创建模式对象 re_weather = re.compile('') re_update_time = re.compile('') weather = re_weather.findall(content) update_time = re_update_time.findall(content) print(weather[0]) print('更新时间:', update_time[0]) life_index = re.compile('<li class="li. hot".*?\n.(.*?)\n(.*?)\n
' '(.*?)
.*?\n', re.S) # re.S使 . 匹配包括换行在内的所有字符 more_weather = life_index.findall(content) # print(more_weather) for item in more_weather: print(item[1], ':', item[0]+",", item[2]) except Exception as e: print("异常", e) return False def get_no(self, cityname): try: print("发送请求:", self.no_url + cityname) response = requests.get(url=self.no_url + cityname, headers=self.headers) content = response.content.decode('utf-8') if len(eval(content)) <= 0: return False content_t = eval(content)[0]["ref"] # print(content_t, type(content_t)) city_no = content_t.split("~")[0] print("%s编号:" % cityname,city_no) return city_no except Exception as e: print("异常", e) return False if __name__ == '__main__': while True: cityname = input("请输入城市名(按Q键结束程序):") if cityname == "Q": break w_spider = WeatherSpider() city_no = w_spider.get_no(cityname) if city_no: w_spider.spider(city_no) else: print("输入有误")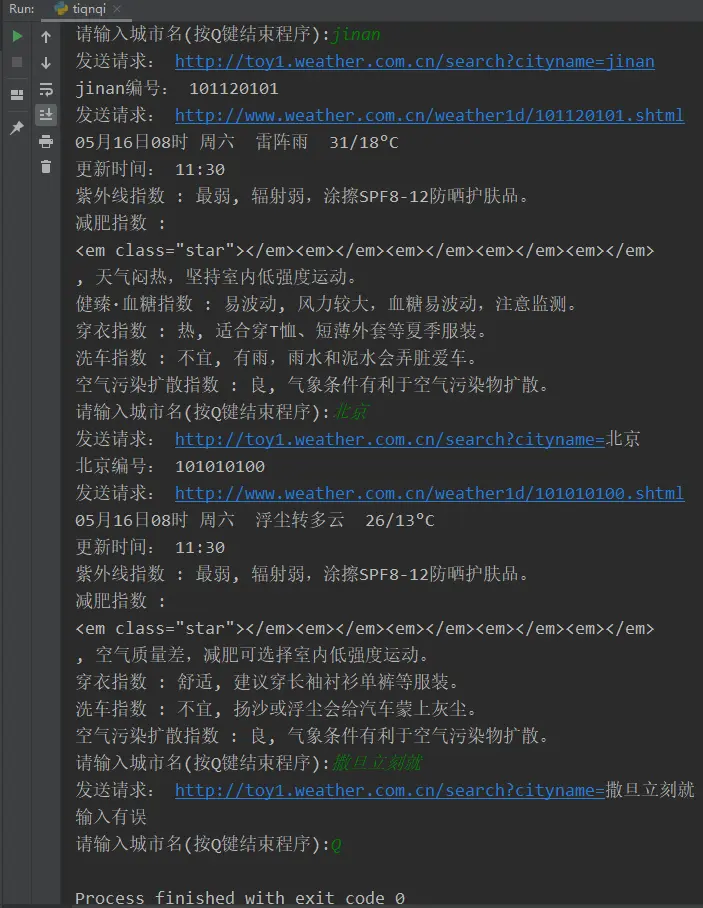
由于中国天气网的反爬机制不是很强,所以整个过程还算比较顺畅,其实中国天气网还有获取7天、15天、40天天气的请求链接,这里就不说了,感兴趣的小伙伴可以去深入了解一下啦。
最后,感谢女朋友在工作和生活中的包容、理解与支持 !
评论
登录后参与技术讨论,分享你的经验与见解。
登录 / 注册暂无评论